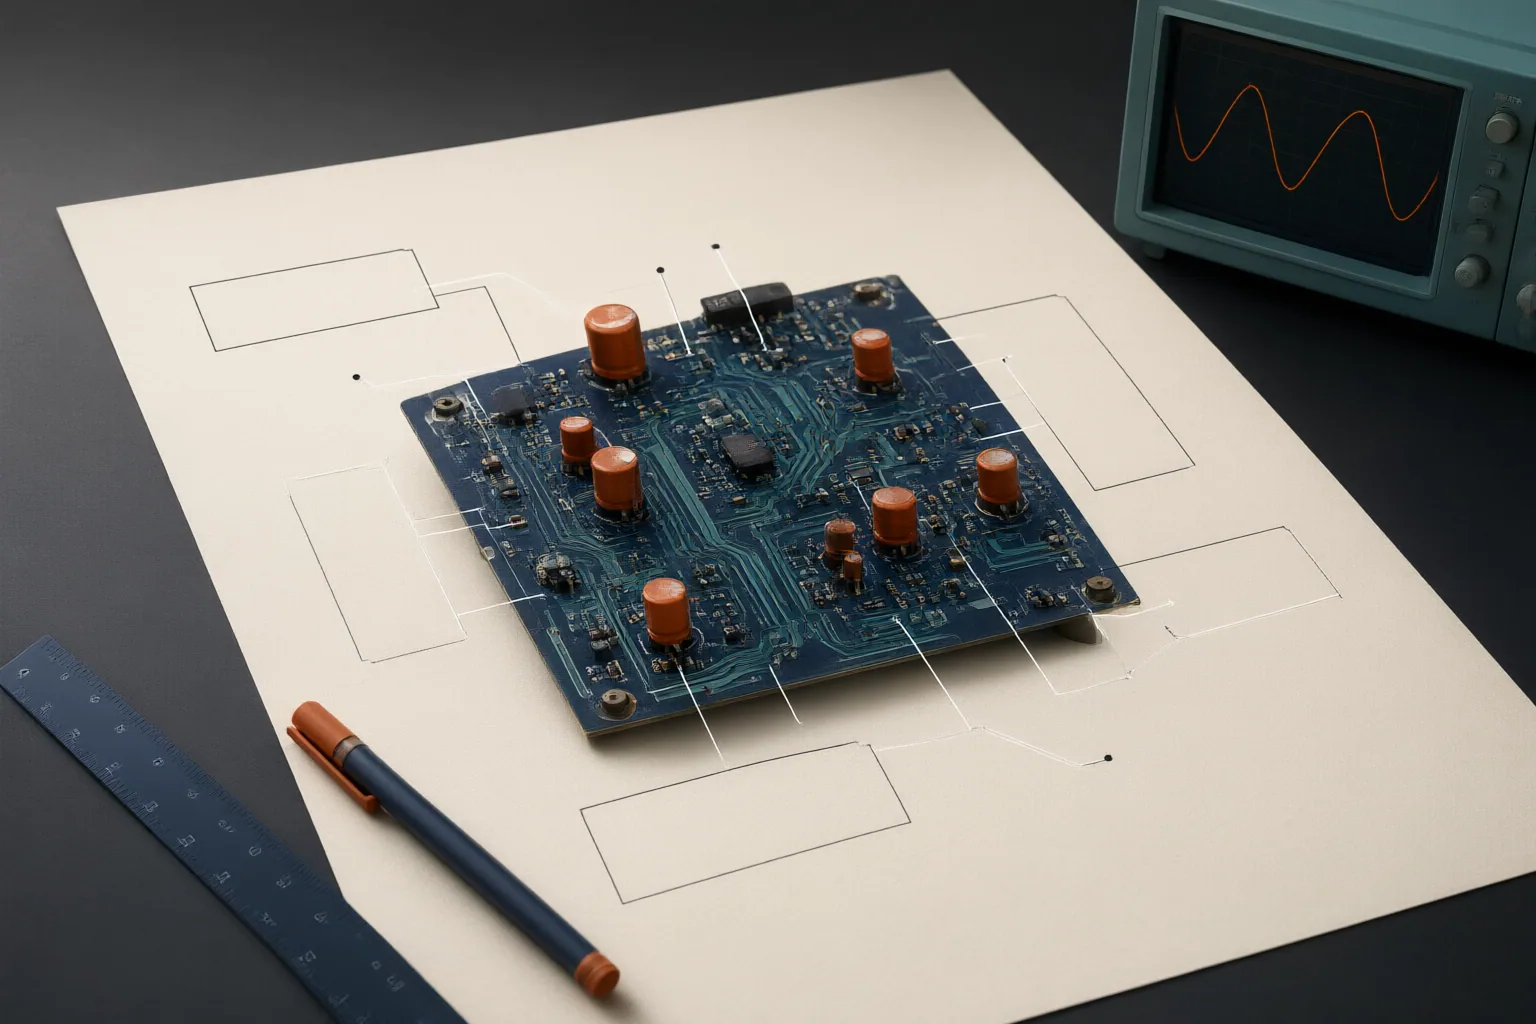
Use captions to state a graphic’s central point, direct labels to identify nearby elements, and keyed callouts when numerous or lengthy explanations would obscure the image. Consistent placement, protected content areas, and precisely targeted connectors help annotations clarify rather than compete with the visual.
Choose the Right Annotation for the Job
Choose each annotation according to what the reader needs from it. A caption describes the graphic, identifies its subject, and helps communicate its central point. Keep it informative but concise; detailed explanations can overwhelm the caption’s primary role.
Labels and callouts serve a narrower purpose: they identify particular elements or features. A short name can sit near the relevant element, while a callout can use a connecting line when proximity alone does not make the relationship clear. Notes can carry supporting explanations or credit when that information does not belong in the caption.
Direct labeling works best when the image contains relatively few items and each label can remain short. If labels become numerous or explanations grow long, placing all that text on the image can hide the content readers are meant to examine. In that situation, replace full labels with compact keyed callouts and put their explanations in a nearby legend. This preserves the connection between each marker and its meaning while moving the heavier text outside the visual.
Place Annotations Close—But Protect the Visual
Place a direct label next to the element it identifies. When the association could still be ambiguous, add a connecting line that clearly reaches the intended feature. Apply the same alignment pattern across related annotations so readers can scan them as an organized system rather than a collection of unrelated additions.
Proximity should not come at the cost of covering essential content. Before placing annotations, identify areas that must remain unobstructed. In an annotated screen tutorial, for example, a presenter’s face inset can be treated as a protected area with explicit clearance around it. Captions may then occupy a defined lower region, while step labels use a different, consistent part of the frame. The particular regions can follow the visual’s composition; the important principle supported by the tutorial example is to assign stable areas and preserve the exclusion zone.
Check the result at the level where it will be read. Confirm that every label remains close enough to its target, every connector has an unmistakable destination, and no caption or step marker covers the content needed to understand the screen. Consistent terminology between the annotations and surrounding explanation also helps readers connect the two.
Reduce Clutter With Keyed Callouts and Precise Targets
A keyed callout replaces an explanation on the image with a compact letter or number. The matching text sits outside the image in a nearby legend. This approach is useful when many parts need identification or when explanations are too long to fit without obscuring the underlying content.
Choose the key system according to meaning. The OxygenXML guidance favors alphabetic keys for items that do not follow a sequence; numbers are appropriate when sequence matters. Whichever system applies, each key should map unambiguously to one legend entry. Keeping the explanations as external text also makes them easier to maintain and localize than wording embedded within the image file.
Precision matters for graphical markers as well as text. In an annotated tutorial, circles and arrows should appear only at specified moments and point to specified targets. Adding markers without a defined purpose can create excess visual noise, while an imprecise arrow may direct attention to the wrong interface element. Review each marker by asking what it identifies, when it is needed, and whether its target is unmistakable. Remove any marker that lacks a described role, and shift longer wording into the legend instead of expanding the on-image callout.
Conclusion
Review annotations as a coordinated system. Each caption, label, callout, or note should have a distinct job: describe the graphic, identify an element, connect a marker to a target, or supply supporting explanation or credit. Use the same terminology in the visual and surrounding text, and align related annotations consistently.
Next, inspect the image itself. Make sure essential content remains visible, protected areas have adequate clearance, connectors reach the correct targets, and arrows or circles appear only where their purpose and timing are defined. If direct labels have become numerous or lengthy, convert them to letters or sequence-appropriate numbers and place the explanations in a nearby legend.
Apply the checklist now: select one annotated visual, remove unnecessary callouts, align the remaining annotations, protect its essential content, and move crowded explanations into a keyed legend.
Disclosures and limitations
- This article was prepared with AI assistance using only the supplied research package and its attributed sources; no products were tested or personally used.
Related reading
- Design & Media Guides for Clear Visual Communication
- Image Export Settings for Sharp Web Graphics Without Unnecessary File Weight
Sources
- Callouts — oxygenxml.com
- ENGL210: Labels, Callouts, Captions, and Notes | Saylor University — dev.sylr.org
- Tutorial caption and callout prompts: label the steps on screen — Vyra